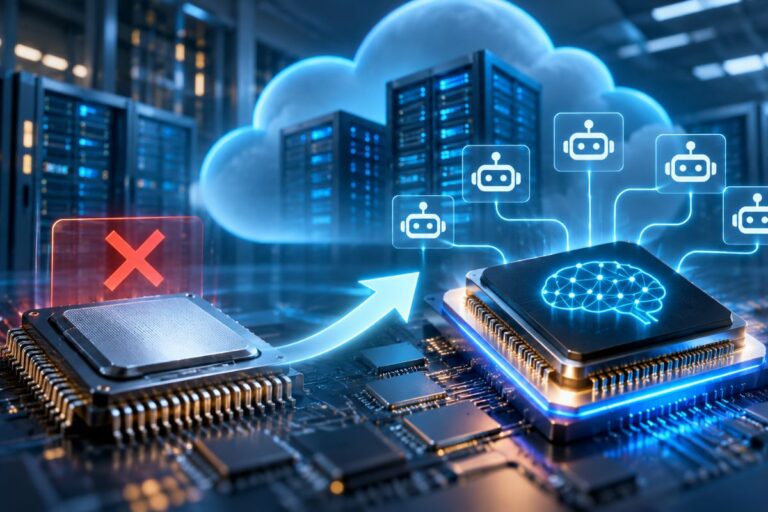
DeepSeek, the Chinese AI research lab that recently disrupted foundation model economics with its open-source R1 release, has collided with a hard limit in Beijing’s push for technological self-reliance. Facing pressure from state industrial planners to train its next-generation reasoning model, R2, entirely on domestic silicon, DeepSeek attempted to replace NVIDIA GPU clusters with Huawei’s Ascend 910B accelerators. The experiment collapsed.
According to sources cited by the Financial Times, DeepSeek experienced severe cluster instability during multi-week distributed training runs. These fundamental technical failures forced the cancellation of R2’s anticipated May launch, compelling DeepSeek engineers to revert to NVIDIA hardware to salvage the training timeline.
Training vs. Inference: The Interconnect Bottleneck
Understanding this failure requires distinguishing AI inference from AI training. While Huawei’s Ascend silicon provides competent throughput for localized FP16 inference—generating responses from a trained model—training massive Mixture-of-Experts (MoE) architectures demands extreme cross-node communication bandwidth.
DeepSeek engineers, collaborating with Huawei systems teams, discovered that the Huawei HCCS interconnect and CANN kernel libraries buckled under the massive weight of all-to-all communication overhead. These inefficiencies caused frequent cluster-wide synchronization timeouts. Training advanced test-time reasoning models—comparable to OpenAI’s o1 architecture—requires flawless mathematical precision across tens of thousands of continuous GPU-hours. A single dropped node risks corrupting the entire checkpoint.
“Our Best Chips Are Still a Generation Behind”
These hardware constraints are openly acknowledged. Earlier this year, Huawei CEO Ren Zhengfei stated directly: “The US has exaggerated Huawei’s achievements… we’re not that great yet. Our best chips are still a generation behind.”
For DeepSeek, this generational gap became an insurmountable physical barrier. China’s industrial regulators enforce strict domestic procurement targets, compelling AI enterprises to formally justify importing NVIDIA’s export-compliant H20 chips, which are governed by US BIS export restrictions. However, domestic accelerators suffer severe memory throughput penalties, standing in stark contrast to Western superclusters that scale seamlessly on NVIDIA Blackwell architectures and NVLink interconnects.
The Pragmatic Retreat to NVIDIA
Confronting mounting delays in a hyper-competitive global AI landscape, DeepSeek management made a pragmatic concession. The company abandoned the Huawei training mandate and returned to NVIDIA systems to rescue the R2 schedule. DeepSeek will continue deploying Huawei hardware for inference workloads, where computational and networking demands are drastically lower.
DeepSeek founder Liang Wenfeng has reportedly voiced frustration over the R2 delays, urging engineering teams to accelerate breakthroughs. This hardware pivot underscores a brutal reality for China’s AI sector: state directives and national ambitions cannot rewrite the laws of compute and network engineering. Achieving genuine self-sufficiency in cutting-edge AI infrastructure requires years of foundational engineering, rather than mandated hardware swaps.
Silicon Architecture & Microbenchmarks: Systems Engineering Implications
From a hardware systems architecture perspective, evaluating modern compute platforms requires examining interconnect bandwidth, thermal dissipation limits, and memory subsystem topology rather than peak theoretical FLOPS alone. In distributed training clusters, compute throughput is routinely throttled not by raw arithmetic logic unit (ALU) density, but by memory wall bottlenecks and bisection bandwidth across the network fabric. High-bandwidth memory (HBM3e) integration, 2.5D/3D chiplet packaging (such as TSMC’s CoWoS), and optical interconnects represent the primary physical determinants of real-world model convergence times.
Data Center Power Delivery, Liquid Cooling, and TCO Metrics
Deploying advanced accelerator architectures imposes severe constraints on modern hyper-scale data center infrastructure. Rack densities exceeding 100 kW to 120 kW mandate a decisive transition away from conventional forced-air cooling toward direct-to-chip liquid cooling or two-phase immersion systems. Facility engineers must balance power usage effectiveness (PUE), fluid loop flow rates, and parasitic pumping power against the operational risks of dielectric fluid degradation. Furthermore, hardware reliability metrics—specifically Mean Time Between Failures (MTBF) of high-speed SerDes links and optical transceivers—dictate checkpointing cadences and cluster-wide compute efficiency.
Enterprise Deployment Architecture & Long-Term Roadmap
For enterprise IT architects and infrastructure operators, mitigating vendor lock-in requires decoupling software pipelines from proprietary hardware primitives. Implementing open accelerator frameworks, hardware-agnostic kernel compilers (such as OpenAI Triton, Modular Mojo, and MLIR abstractions), and standardized workload orchestrators (Kubernetes with custom device plugins) ensures enterprise software stacks can dynamically schedule compute across heterogeneous silicon fabrics without costly architectural refactoring.